Sam Altman Argues Cloud Data Centers Use Scarce AI Memory More Efficiently
- Gate
- AI & ML
- Departs
- Crew
- Andrew E. Freedman
- Passengers
- 507
Altman says cloud pooling can keep scarce DRAM busier than home PCs. The case depends on demand, data center growth and what users value.
Sam Altman’s argument against running AI models on home computers comes down to memory utilization: a shared data center can keep DRAM working across many users, while memory in a personal computer may sit idle for much of the day. That’s a real efficiency question for a supply-constrained industry. It’s also an argument that favors the cloud model OpenAI relies on, and it leaves out tradeoffs that matter to people who want to run models locally.
In an interview with the YouTube channel Cheeky Pint, Altman discussed the prospect of people using open-source models on computers they already own or plan to build. At about the 29-minute mark, he said: “From a global allocation perspective, actually, it's quite terrible to have everybody have a bunch of the world's limited supply of DRAM sitting in their own computer and being used 5% of the time.” He argued that maximizing utilization in the cloud makes more sense when memory supply is constrained.
The 5% figure is Altman’s characterization of how often memory in personal computers is used for AI, not a measurement supplied in the article. His broader point is about pooling capacity: a data center can serve requests from many customers using a shared fleet, while each home system is available to its owner alone. If that fleet can keep its memory busy, the same installed capacity may support more work across the day.
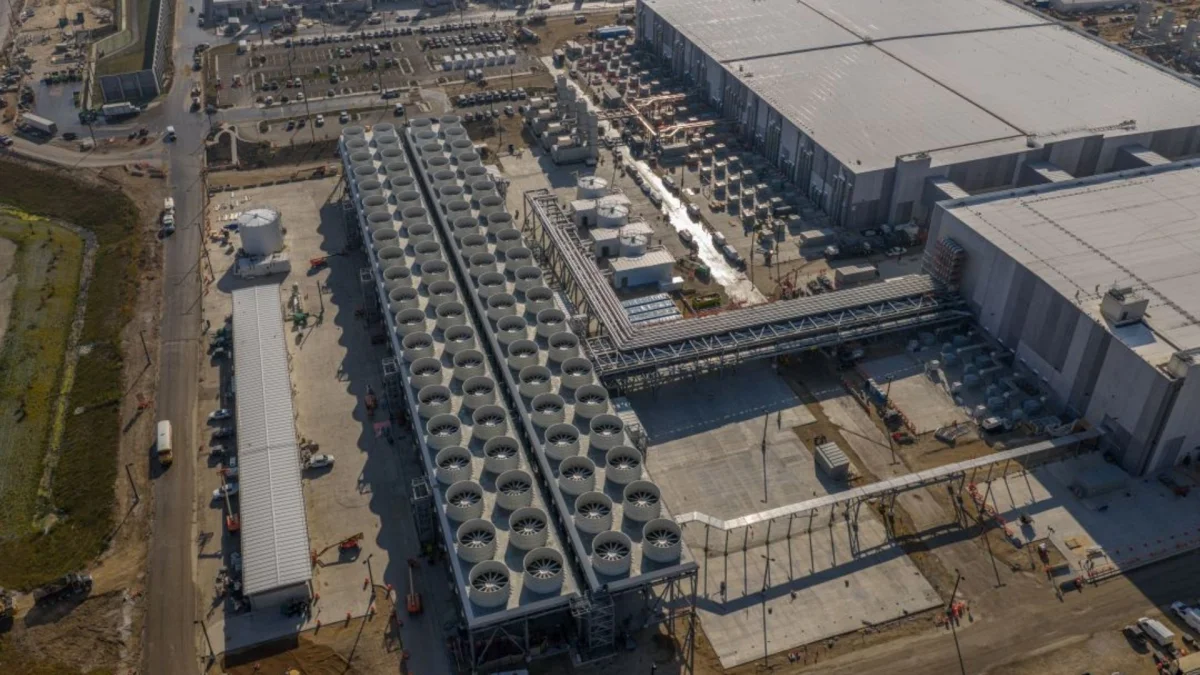
Utilization is only one part of the comparison
Altman’s case treats scarce DRAM as a resource that should be assigned wherever it can spend the most time serving AI workloads. That framing is persuasive if the main goal is to maximize use of a limited supply. It doesn’t, by itself, settle whether cloud inference is better for every user or task.
A personal computer’s memory serves more than one purpose. People use it for work, web browsing, games and other applications, and it can support local AI when they choose to run it. A cloud system pools hardware across customers, but that arrangement also means the user depends on a remote service to provide the model and computing capacity. The interview excerpt makes the case for shared utilization; it doesn’t compare the full costs, performance or practical constraints of the two approaches.
For an individual, the question isn’t simply whether their RAM is busy every minute. It’s whether having a capable computer at home offers enough value for their own mix of tasks. Local inference can make use of hardware already on hand, while cloud inference shifts the computing work to a provider’s data center. The source doesn’t provide model requirements, operating costs or performance figures that would let readers calculate which option is cheaper in a particular case.
The business model shapes the argument
OpenAI offers some open-source models, but its main business centers on closed-source models running in data centers. Altman’s comments therefore align with a service model in which customers access AI through cloud infrastructure. Wider use of local models could give some users another way to get AI assistance and, depending on their hardware and needs, reduce their reliance on paid services.
That possibility is still conditional. The interview doesn’t establish that local models will match the capabilities of the company’s hosted offerings, or that home systems will become a practical substitute for them. It does show why the distinction matters: if more useful AI can run on hardware people own, the provider’s role may shift; if the best experience continues to depend on large shared systems, cloud services retain an advantage.
Altman’s reasoning also assumes that data center construction will continue and that memory used there around the clock is more valuable than memory installed in personal computers. Those are assumptions, not outcomes demonstrated in the interview. If demand, available supply or the pace of infrastructure expansion changes, the balance behind his argument could change too.
What to watch
The practical test will be whether local models become capable enough for tasks people actually want to run, and whether the cost and convenience compare favorably with hosted access. On the infrastructure side, the relevant question is whether data centers can keep their memory busy enough to justify directing more supply toward them. The interview offers an argument for that approach, but no figures that settle the comparison.
For engineers and buyers, the useful takeaway is to treat memory utilization as one factor in a larger choice. Cloud pooling can make shared hardware available across many users; local hardware gives its owner direct control over when and how to use it. As local models and data center capacity develop, the tradeoff will depend on real workload needs, costs and capability—not utilization alone.
Related coverage
- The data center cooling state of play
- The custom AI ASIC state of play
- America’s AI chip rules keep changing — and the rest of the world is paying the price
- GTC 2026: Ian Buck press Q&A transcript — VP of Hyperscale and HPC speaks out on shelving CPX and shipping LPU decode this year
- Demand for data center CPUs has surged, and AI agents are responsible


