Skip to departures
Development
 Intel’s PC Forecast Sends Semiconductor Stocks Into a $1 Trillion Selloff
Intel’s weaker PC outlook helped drive a broad chip selloff, while Apple’s smaller decline showed how product mix can shape investor exposure.
GateAnalytics
Departs
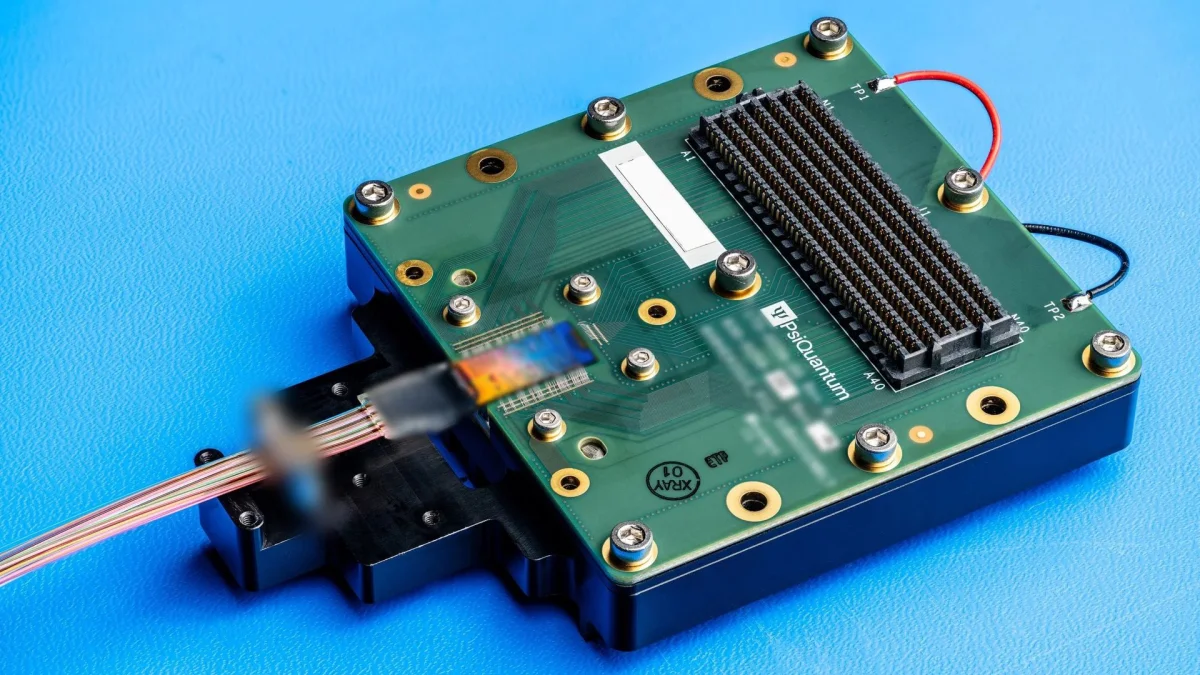 PsiQuantum’s 1.2 dB Optical Switch Targets AI GPU Networks
PsiQuantum’s compact switch posts low signal loss without amplification. Its next test is scaling to the port counts used in data centers.
GateAI & ML
Departs
 LLM Inference Explained: Weights, Quantization, KV Cache and More
A practical guide to LLM memory and inference, from model weights and context limits to retrieval, expert routing and token generation.
GateAI & ML
Departs
 AI Agents Push Chip Design Earlier, but Verification Still Sets the Pace
AI agents and digital twins widen early design exploration, while model accuracy, formal proof and changing workloads keep verification central.
GateAI & ML
Departs
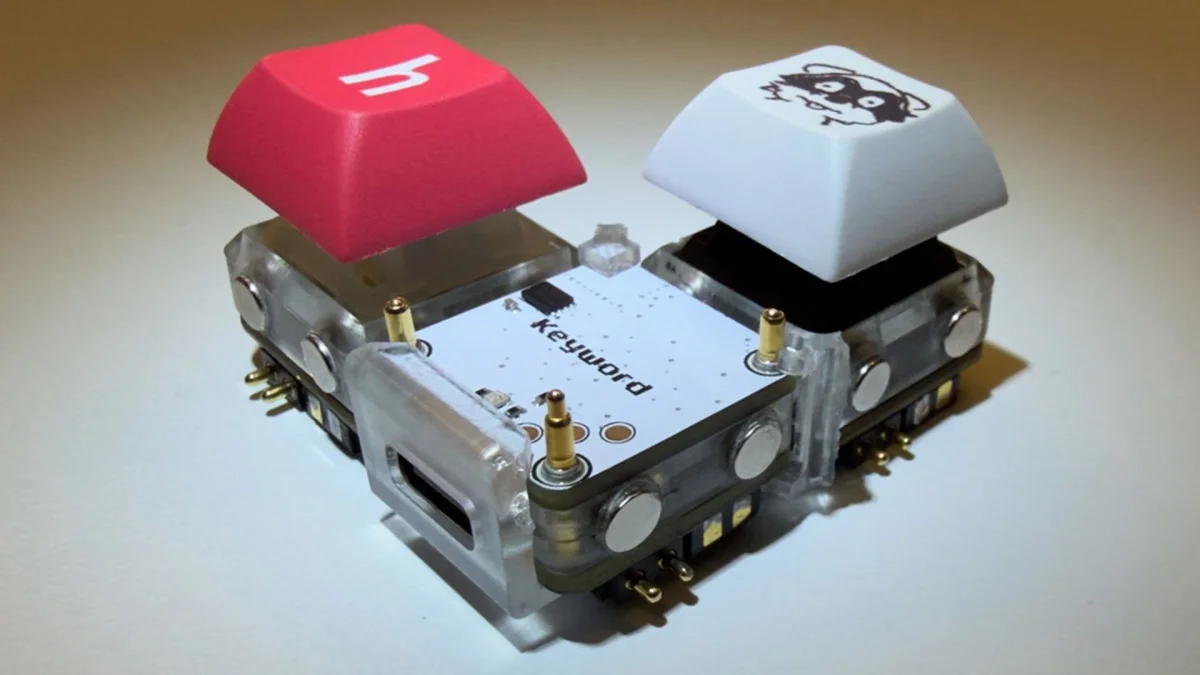 Keybytes Keyboard Uses Modular, Microcontroller-Equipped Keys for Custom Layouts
Keybytes connects magnetic, 1U keys to a central hub, offering unusual layout flexibility with a steep build cost and substantial assembly work.
GateAnalytics
Departs
 Railway Security Incident: Impact, Timeline and Credential Rotation Guidance
Railway says up to 1.85% of workspaces may have had encrypted variables exposed. Builds paused during response; customer applications stayed online.
GateAI & ML
Departs
 Elastic Search and Observability Support Audi Revolut F1 Engineering Investigations
Audi Revolut F1 uses Elastic to search engineering software logs and telemetry, with broader Search and Observability work planned from 2027.
GateAI & ML
Departs
 AI-Assisted Cybercrime: How One Operator Used Hermes and DeepSeek Across Attacks
A single operator used AI for university intrusions, VoIP fraud planning, Wi-Fi cracking and crypto research, exposing the risks of low-friction tools...
GateAI & ML
Departs
 Elastic Reports Faster Jina Model Inference on NVIDIA RTX Pro 6000 GPUs
Elastic reports up to 8x lower embedding latency and faster reranking and OCR after moving some Jina API models to RTX Pro 6000 GPUs.
GateAI & ML
Departs
 Autonomous Chip Design Advances From RTL Generation Toward Full Workflow Orchestration
AI agents can now turn some customer specifications into verified RTL, while physical implementation and final chip approval still need to advance.
GateAI & ML
Departs
 Declarative Deployment Configs: Railway, Render, Fly.io, Vercel and Netlify Compared
Compare deployment configuration across five platforms, from full-stack resource definitions to frontend builds, and see where extra provisioning stil...
GateAI & ML
Departs
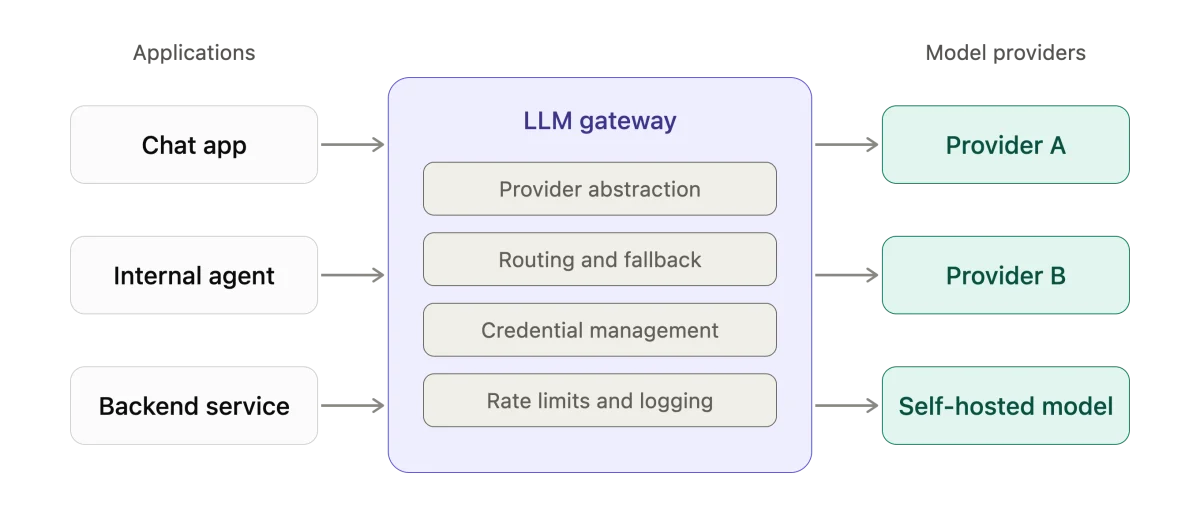 LiteLLM Vulnerabilities Exposed Configuration, Credentials and Runtime Code
A flaw in LiteLLM’s configuration endpoint enabled file access, admin takeover and code execution; a separate routing issue exposed provider credentia...
GateAI & ML
Departs
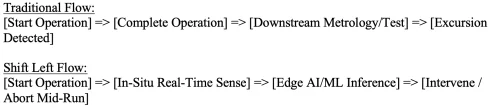 Semiconductor Fabs Move Yield Detection Closer to the Process—and Strain Data Systems
Real-time sensor analytics can catch process drift sooner, but fabs need richer data links and context to make module-level AI useful across productio...
GateAI & ML
Departs
 Elastic Observability Study Reports Lower Downtime and Infrastructure Costs
A Forrester study models how Elastic Observability affected downtime, engineering time, customer retention and infrastructure costs at a large enterpr...
GateAnalytics
Departs
 Elastic’s September 2026 Developer Update: OCR, Agent Controls and Faster RAG
Elastic’s September update covers layout-aware OCR, a policy-scoped CLI for agents, lower-cost retrieval and new LLM tracing in APM.
GateAI & ML
Departs